v0.2:不到四千行的调度核心跑出 3.1 倍
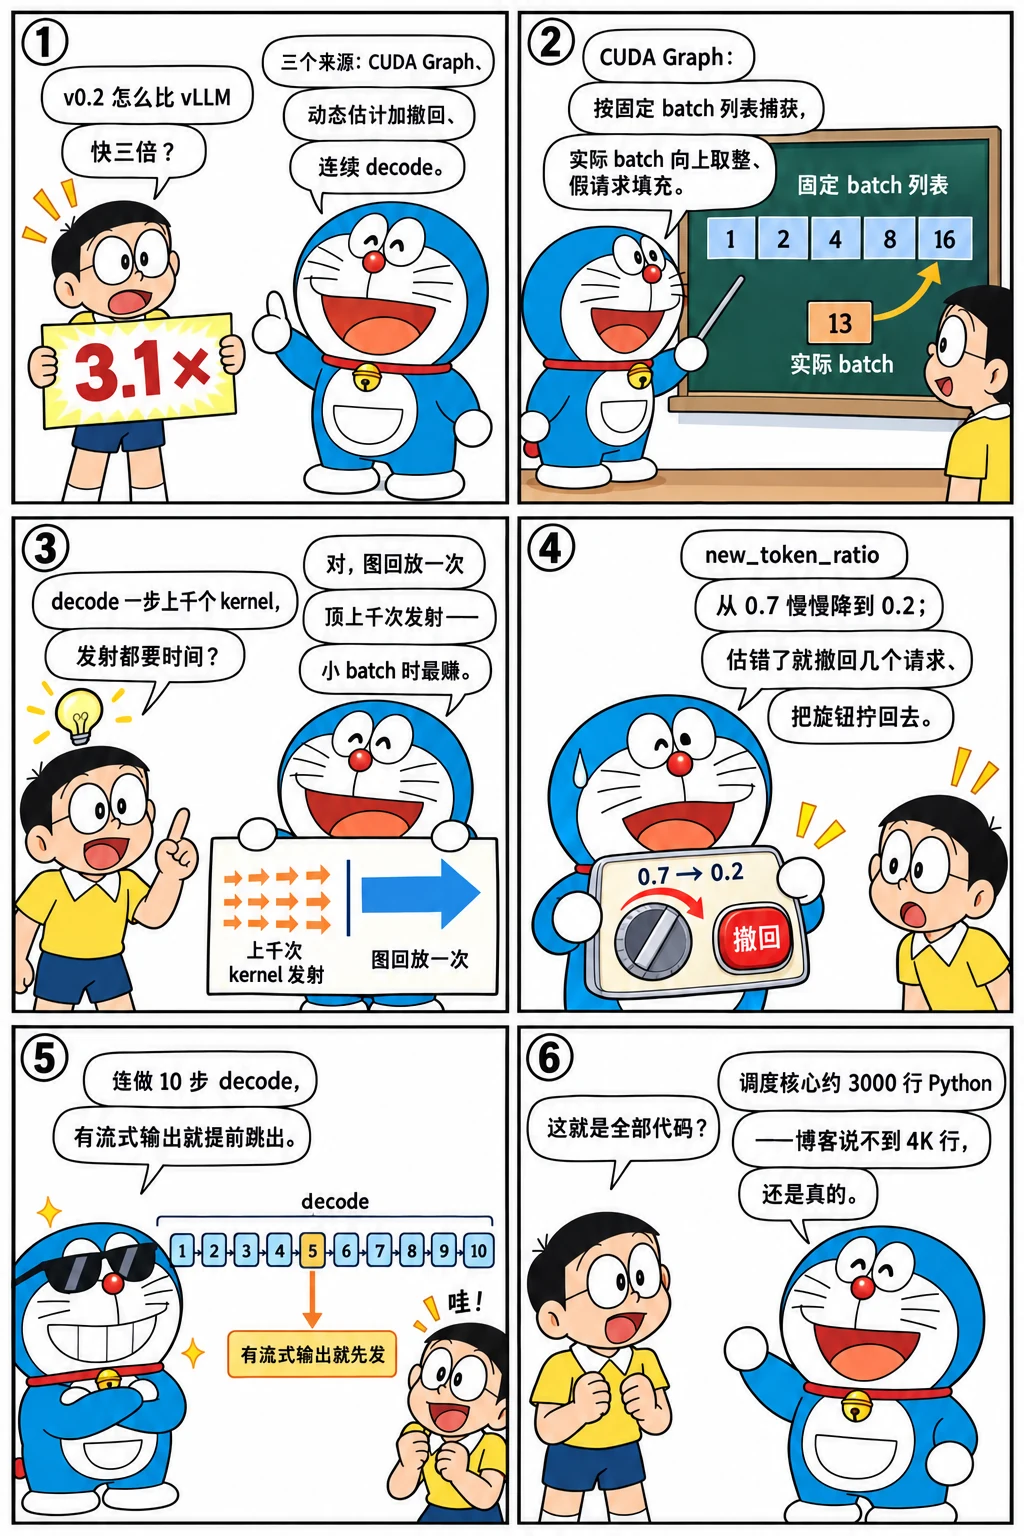
2024 年 7 月 25 日,SGLang 打出 v0.2.0 并发了一篇博客:在 Llama-70B 上吞吐最高是 vLLM 的 3.1 倍,常常追平甚至超过 TensorRT-LLM;而"核心调度器不到 4000 行 Python"。这一章读 v0.2.0 的代码,找出 3.1 倍的来源:默认开启的 CUDA Graph、动态估计的 new_token_ratio 与撤回机制、连续 decode 与流式的平衡,以及发布前后几天接连进来的 bench_serving、DeepSeek-V2 和分块 prefill。这也是 SGLang 从"论文的运行时"变成"推理引擎"的分水岭:博客里"语言"几乎不再出现。
自测:能答上来就可以跳过本章
- v0.2 博客的对比设置是什么?"不到 4K 行"指哪些文件?
- CUDA Graph 在 v0.2.0 里怎么用:捕获哪些 batch 大小、怎么处理不在列表里的 batch、为什么要求 FlashInfer?
new_token_ratio是什么?它在一次服务过程中怎么变化?撤回(retract)在什么时候发生?- 分块 prefill 是 v0.2.0 的功能吗?它和 v0.2 的关系是什么?
自测参考答案(先自己答,再展开对照)
- Llama-8B / 70B / 405B,A100 和 H100,BF16 与 FP8,基线 vLLM 0.5.2 和 TensorRT-LLM v0.10.0,用
bench_serving.py压测。"不到 4K 行"指managers/controller/下的调度核心:tp_worker.py、infer_batch.py、radix_cache.py、schedule_heuristic.py、cuda_graph_runner.py、model_runner.py和两个 controller,加起来约 3000 行。 - 启动时对
[1, 2, 4, 8, 16, …, 128]这些 batch 大小各捕获一张图(decode 专用);运行时把实际 batch 向上取整到最近的捕获大小,多出来的槽位用长度 1 的假请求填充,回放后截掉多余的输出。因为 FlashInfer 的 decode wrapper 支持use_cuda_graph=True(固定的 indptr / indices 缓冲区),Triton 后端当时没有这个接口,所以--disable-flashinfer时也禁用 CUDA Graph。 - 对"运行中的请求还会生成多少 token"的估计系数:准入时用它乘以剩余的
max_new_tokens预留空间。初始 0.7,每步 decode 成功就衰减 0.001 直到下限(默认 0.2,按上下文长度换算),一旦 decode 时显存不够就撤回部分请求并把系数调高。撤回发生在forward_decode_batch开头的check_decode_mem失败时,按输出长度排序撤回最新的请求放回等待队列。 - 不是:#800 在 7 月 29 日合入,v0.2.0 是 25 日打的。它是 v0.2 系列的一部分(v0.2.x),博客没有提它。
先看一个六格小剧场,再读正文:
一个版本的体量
echo "v0.2.0:$(git log -1 --date=short --format='%ad %h %s' v0.2.0 | cut -c1-70)"
echo "v0.1.5 → v0.2.0 的提交数:$(git rev-list --count v0.1.5..v0.2.0)"
echo "这段时间提交最多的作者:"; git shortlog -sn v0.1.5..v0.2.0 | head -6
v0.2.0:2024-07-25 1a491d00cb Bump version to 0.2.0 (#730)
v0.1.5 → v0.2.0 的提交数:408
这段时间提交最多的作者:
   131  Lianmin Zheng
    66  Liangsheng Yin
    59  Ying Sheng
    22  zhyncs
    17  Cody Yu
    11  Yineng Zhang
半年、几百个提交、十来个主要作者——比起 1 月的"四个人的论文代码",这已经是一个社区项目。博客的原话:"在 LMSYS.org,我们运营 Chatbot Arena 已经一年多……SGLang 已被 Chatbot Arena 用于服务部分模型,也被 Databricks、若干创业公司和研究机构使用,生成了数万亿 token";"核心调度器在不到 4K 行代码里实现";"SGLang 高效的 Python 批调度器扩展性很好,常常追平甚至超过 C++ 实现的闭源系统"。数一数那不到 4K 行:
total=0
for f in $(git ls-tree -r --name-only v0.2.0 -- python/sglang/srt/managers/controller); do
  n=$(git show "v0.2.0:$f" | wc -l); total=$((total + n)); printf '%5d  %s\n' "$n" "${f#python/sglang/srt/managers/}"
done
echo "合计 $total 行"
  240  controller/cuda_graph_runner.py
  935  controller/infer_batch.py
  202  controller/manager_multi.py
  157  controller/manager_single.py
  383  controller/model_runner.py
  272  controller/radix_cache.py
   70  controller/schedule_heuristic.py
  800  controller/tp_worker.py
合计 3059 行
来源一:默认开启的 CUDA Graph
7 月 13 日的 #612 "Enable cuda graph by default" 加了 cuda_graph_runner.py(173 行)。ModelRunner.init_cuda_graphs 决定捕获哪些 batch:
[1, 2, 4] + [8, 16, …, 128],--disable-flashinfer 时不捕获。捕获和回放:
        def run_once():
            input_metadata = InputMetadata.create(
                self.model_runner,
                forward_mode=ForwardMode.DECODE,
                req_pool_indices=req_pool_indices,
                seq_lens=seq_lens,
                prefix_lens=None,
                position_ids_offsets=position_ids_offsets,
                out_cache_loc=out_cache_loc,
                return_logprob=False,
                top_logprobs_nums=0,
                skip_flashinfer_init=True,
            )
            input_metadata.flashinfer_decode_wrapper = flashinfer_decode_wrapper

            return forward(input_ids, input_metadata.positions, input_metadata)

        for _ in range(2):
            run_once()

        torch.cuda.synchronize()
        with torch.cuda.graph(graph, pool=self.graph_memory_pool, stream=stream):
            out = run_once()
        torch.cuda.synchronize()
        self.graph_memory_pool = graph.pool()
        return graph, None, out, flashinfer_decode_wrapper
...
    def replay(self, batch: Batch):
        assert batch.out_cache_loc is not None
        assert not batch.return_logprob
        raw_bs = len(batch.reqs)

        # Pad
        index = bisect.bisect_left(self.batch_size_list, raw_bs)
        bs = self.batch_size_list[index]
        if bs != raw_bs:
            self.seq_lens.fill_(1)
            self.position_ids_offsets.zero_()
            self.out_cache_loc.zero_()

        # Common inputs
        self.input_ids[:raw_bs] = batch.input_ids
        self.req_pool_indices[:raw_bs] = batch.req_pool_indices
        self.seq_lens[:raw_bs] = batch.seq_lens
        self.position_ids_offsets[:raw_bs] = batch.position_ids_offsets
        self.out_cache_loc[:raw_bs] = batch.out_cache_loc

        # FlashInfer inputs
        init_flashinfer_args(
            ForwardMode.DECODE,
            self.model_runner,
            self.req_pool_indices[:bs],
            self.seq_lens[:bs],
            None,
            self.flashinfer_handlers[bs],
        )

        # Replay
        self.graphs[bs].replay()
        output = self.output_buffers[bs]
关键在三处:输入缓冲区(input_ids、req_pool_indices、seq_lens、out_cache_loc、FlashInfer 的 kv_indptr / kv_indices)在初始化时按最大 batch 分配一次,图里的 kernel 读的永远是这些地址;replay 时把实际 batch 复制进缓冲区前部、不足的部分填充(seq_lens 填 1、out_cache_loc 填 0,让假请求"写到槽位 0"而不出错),回放后把输出截到实际 batch;所有图共用一个内存池(graph_memory_pool),不同 batch 大小的图不重复占显存。捕获前先跑两遍预热(for _ in range(2): run_once()),让 FlashInfer 的 plan 和 PyTorch 的缓存分配稳定下来。
decode 一步只有几十毫秒甚至几毫秒,却要发射几百上千个 kernel;Python 逐个发射的开销在小 batch 时能占到一半以上,CUDA Graph 把它压成一次 replay()。这是 v0.2 在小 batch、低延迟场景下赢 vLLM 最多的原因之一(vLLM 当时也有 CUDA Graph,但默认关闭、且和它的 block table 配合得更复杂)。
来源二:动态的 new_token_ratio 与撤回
初版的准入用固定系数 0.4 估计运行中请求还会生成多少(第二章)。v0.2.0 把它变成一个随运行调整的量:
        available_size = (
            self.token_to_kv_pool.available_size() + self.tree_cache.evictable_size()
        )
        if self.running_batch:
            available_size -= sum(
                [
                    (r.sampling_params.max_new_tokens - len(r.output_ids))
                    * self.new_token_ratio
                    for r in self.running_batch.reqs
                ]
            )
...
    def forward_decode_batch(self, batch: Batch):
        # Check if decode out of memory
        if not batch.check_decode_mem():
            old_ratio = self.new_token_ratio

            retracted_reqs, new_token_ratio = batch.retract_decode()
            self.new_token_ratio = new_token_ratio

            logger.info(
                "decode out of memory happened, "
                f"#retracted_reqs: {len(retracted_reqs)}, "
                f"#new_token_ratio: {old_ratio:.4f} -> {self.new_token_ratio:.4f}"
            )
            self.forward_queue.extend(retracted_reqs)
        else:
            self.new_token_ratio = max(
                self.new_token_ratio - self.new_token_ratio_decay,
                self.min_new_token_ratio,
            )
准入时的估计公式没变(可用 = 空闲 + 可淘汰 − Σ 剩余 × 系数),变的是系数:开始保守(0.7),每成功 decode 一步就衰减 0.001,直到下限 min_new_token_ratio(按模型上下文长度换算,默认 0.2)——请求跑得越久、系统越确信"大多数请求不会用完 max_new_tokens",就越敢多接。估计失败时有后手:check_decode_mem 发现 decode 分配不出槽位,就 retract_decode 撤回一部分请求(按输出长度排序,撤回最新的),把它们放回等待队列,并把系数调高(new_token_ratio_recovery)。撤回的机制 1 月 20 日的 #36 "Fix the possible bug of decode out of memory" 就有了,v0.2.0 把它和系数的升降闭环起来。
这是 SGLang 和 vLLM 调度哲学差别最具体的地方:vLLM "能分配就接收,不够再抢占",SGLang "预估未来、保守接收、估错了撤回"。两者都能避免死锁;SGLang 的做法在请求长度相近时抢占更少,在长度差异大时更依赖系数的自适应。
来源三:连续 decode 与流式的平衡
初版硬编码的"连做 10 步 decode"变成了 global_config.num_continue_decode_steps(仍是 10),但多了一个出口:if self.out_pyobjs and self.running_batch.has_stream(): break——有流式请求且已经攒出了输出,就提前跳出去发送。这是吞吐(少回 Python 层、少收请求)和流式延迟之间的折中;没有新请求时还会 check_memory 自检并把系数重置为初值。真正消灭"连做 N 步"的是 10 月的重叠调度(第 12 章):CPU 工作被藏到 GPU 后面之后,每步回 Python 层的代价就不再重要。
发布前后那两周
v0.2.0 不是一个孤立的 tag,它前后两周的提交说明了作者在忙什么:
for h in 665815969a c126a6ccba d774acad5c eedc12e12e 679ebcbbdc cdcbde5fc3 7cd4f244a4 e1eae1fd15; do
  git log -1 --date=short --format='%ad  %h  %s' $h | cut -c1-96
done
2024-07-13  665815969a  Enable cuda graph by default (#612)
2024-07-20  c126a6ccba  feat: add benchmark serving (#657)
2024-07-18  d774acad5c  Remove the dependency of rpyc (#646)
2024-07-21  eedc12e12e  Support Deepseek MoE Model (#689)
2024-07-26  679ebcbbdc  Deepseek v2 support (#693)
2024-07-29  cdcbde5fc3  Code structure refactor (#807)
2024-07-29  7cd4f244a4  Chunked prefill (#800)
2024-08-05  e1eae1fd15  Support MLA for DeepSeek-V2 with Triton - step 1 (#905)
- #657 bench_serving(7 月 20 日):博客里的数字来自这个脚本(它是 vLLM 的
benchmark_serving.py的改编,后来 vLLM 又参考了它的random数据集)。有了统一的压测工具,"3.1 倍"才可比。 - #689 DeepSeek MoE、#693 DeepSeek-V2(7 月 21、26 日):下一个阶段的主角提前登场,8 月 5 日就开始了 MLA 的 Triton 实现(第 11 章)。
- #800 分块 prefill(7 月 29 日):长提示词不再独占一步,被切成
--chunked-prefill-size的块和 decode 混跑;schedule_heuristic.py的准入逻辑随之改动。这是 2024 Q3 路线图(issue #634)里的条目之一。 - #807 目录重构(同一天):为后面的
scheduler.py独立铺路。
博客末尾的预告是"长上下文和 MoE 优化",正是 v0.3 的主题。
设计取舍
- CUDA Graph 只给 decode,而且绑定 FlashInfer。 prefill 的形状变化太多,不值得捕获;为了让图可回放,注意力后端必须接受固定缓冲区——这个要求后来成为所有注意力后端的接口约定(
init_cuda_graph_state/init_forward_metadata_capture_cuda_graph)。 - 估计 + 撤回,而不是抢占。 实现简单(撤回 = 放回队列,KV 还在树里可以命中),但估计系数是全局的,对混合负载不够精细;后来加了
--schedule-conservativeness让用户调它。 - Python 调度器。 博客把"Python 实现也能追平 C++"当作卖点。代价要到 batch 很大、每步只有几毫秒时才显现,那是 v0.4 零开销调度要解决的问题。
后来怎么样了
- CUDA Graph:捕获的 batch 列表、填充方式和内存池共享沿用至今;2025 年加了 piecewise CUDA graph(#11490,把 prefill 的非注意力部分也图化)和投机解码的图。
new_token_ratio系列参数今天还在global_config.py和schedule_policy.py里,retract_decode仍是显存不足时的第一反应。num_continue_decode_steps在重叠调度成为默认后失去意义,相关逻辑被移除。bench_serving.py成为 SGLang 和 vLLM 共同使用的压测工具之一,也是本手册推理系统篇的压测一章讲的脚本。
练习
1. 填充的代价。 根据 replay 的实现,batch 为 65 时会回放哪张图?浪费多少计算?什么样的 batch 列表能减少浪费、又不让捕获时间和显存失控?
参考答案
向上取整到 72(列表是 1、2、4、8、16、…、128,步长 8),7 个假请求约浪费 10% 的 decode 计算。更密的列表(小 batch 步长小、大 batch 步长大)能减少浪费,代价是捕获时间(每张图几百毫秒)和图的显存;后来的版本正是这样配置的。
2. 系数的走向。 假设一批请求都在 2000 步内结束且从未撤回,new_token_ratio 的轨迹是什么?如果每 100 步撤回一次呢?
参考思路
从 0.7 每步减 0.001,700 步后到 0.2(下限不低于 base_min_new_token_ratio 换算值);此后保持下限。频繁撤回会反复把系数抬回更高的值(new_token_ratio_recovery),系统在"多接"与"撤回"之间震荡,吞吐下降——这就是为什么估计系数要能衰减、也要能恢复。
3. 验证博客的"不到 4K 行"。 用 v020-core-lines.sh 的结果判断博客的说法指的是哪个范围;把 mem_cache 里的 memory_pool.py 和 layers/ 的注意力 kernel 加进去又是多少。
参考思路
controller 目录约 3000 行,符合"不到 4K";加上 memory_pool.py(约 100 行)和三个 Triton 注意力文件(约 900 行)仍在 4K 左右。说法成立,但不包含模型文件和服务层。
怎么讲清楚
"SGLang 为什么快?"——不要只答 RadixAttention。按 v0.2 的三个来源讲:CUDA Graph 消灭小 batch 的发射开销;预估 + 撤回的准入让显存用得满又不死锁;连续 decode 减少 Python 层的往返。再补一句"这些都是在 3000 行 Python 里做到的",以及后来零开销调度把 Python 开销彻底藏起来——这样讲能体现你读过代码而不是博客标题。
小结
- v0.2.0(2024-07-25):Llama-70B 上吞吐最高 3.1 倍于 vLLM 0.5.2,调度核心约 3000 行。
- 三个来源:默认 CUDA Graph(固定缓冲区 + 填充 + 共享内存池)、动态
new_token_ratio+ 撤回、连续 decode 与流式的平衡。 - 发布前后两周:bench_serving、DeepSeek-V2、分块 prefill、目录重构——下一阶段的种子都在这里。
发现错误或有更好的写法?在 GitHub 上编辑此页提交问题