压缩 FSM 与跳跃解码:结构化输出的三代后端
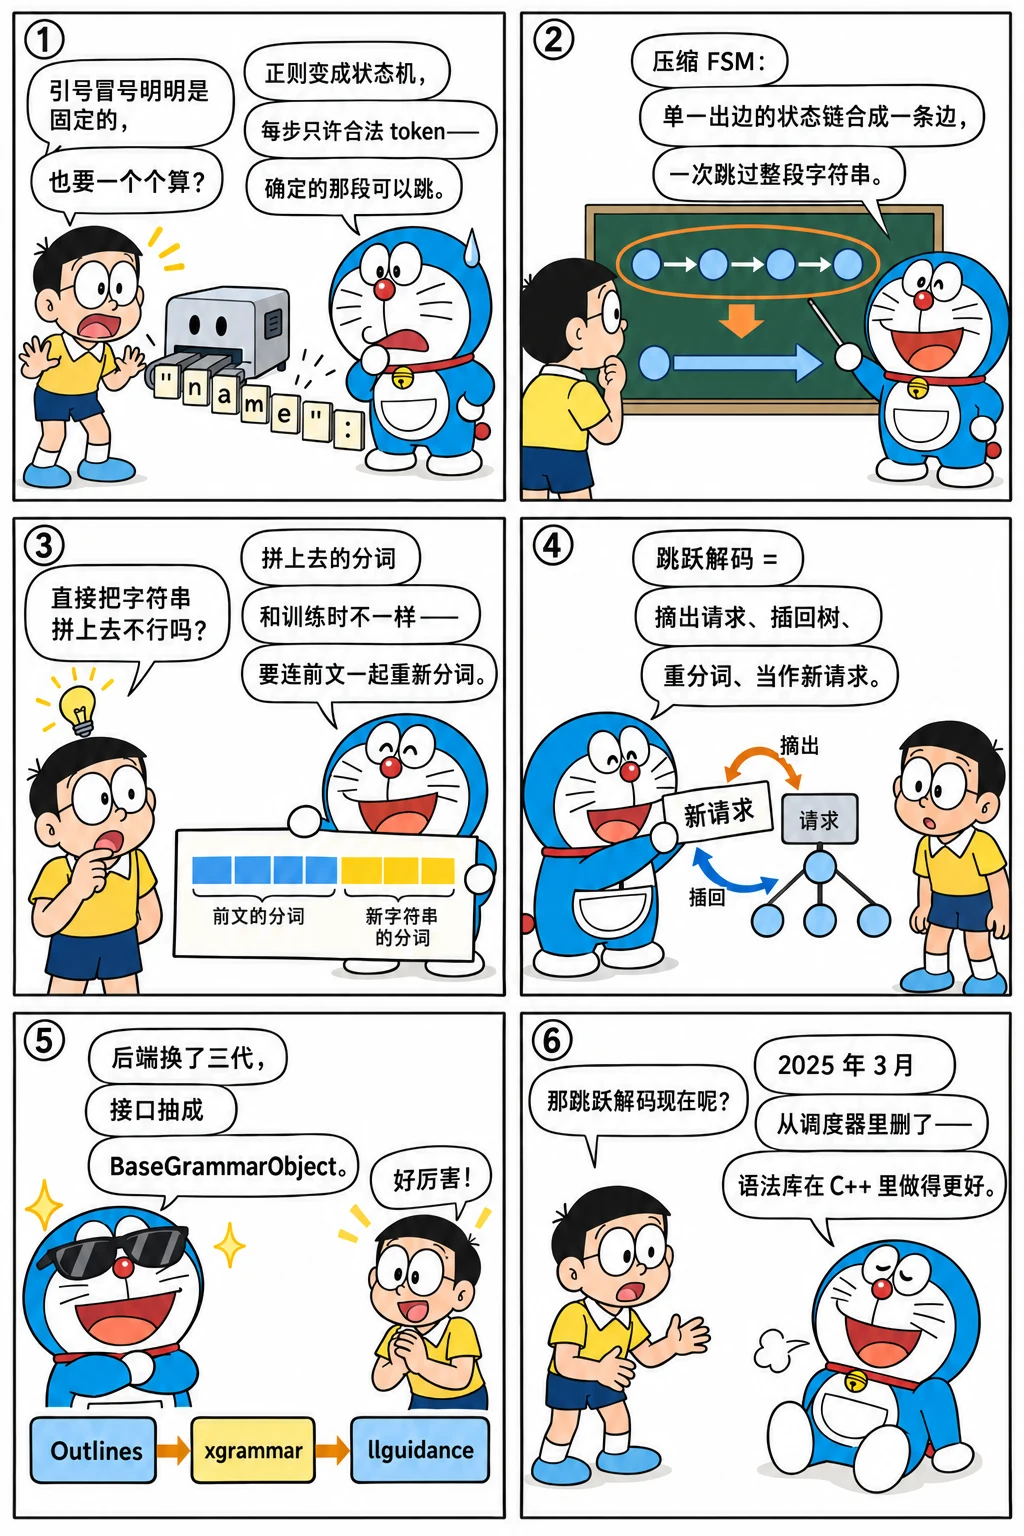
论文的第二个运行时技术是压缩有限状态机:JSON 里大段确定的文本不必一个 token 一个 token 地生成,可以整段"跳"过去。它的代码史很有意思:初版从 Outlines 复制了 FSM 实现并在采样时做掩码;三周后加上 jump-forward;一个月后把复制的代码换回 Outlines 库;2024 年 10 月引入 xgrammar、2025 年 2 月引入 llguidance、同年 3 月把调度器里的 jump-forward 整个删掉——因为语法库自己做得更好。这一章顺着这条线读,看一个论文想法怎样被工程现实重塑。
自测:能答上来就可以跳过本章
- 正则约束解码的基本做法是什么?每一步需要多少计算?
- jump-forward 跳的是什么?为什么跳过之后要重新分词?
- 初版把 FSM 编译放在哪里?为什么要放后台线程?
- 为什么 2025 年 3 月把 jump-forward 从调度器里删掉了?今天这个功能在哪里?
自测参考答案(先自己答,再展开对照)
- 把正则编译成确定有限状态机,再为每个状态预计算"哪些 token 是允许的"(token 的字符串从该状态出发能被 FSM 接受);每一步把不允许的 token 的 logit 设为负无穷,采样后用选中的 token 推进状态。预计算是一次性的(和词表大小成正比),每步只是一次掩码。
- 跳的是 FSM 里一串"只有一条出边"的状态对应的字符串(比如 JSON 里的
", "age":);这些字符是确定的,不需要模型决定。但直接把它们当作新 token 拼上去会得到和训练时不同的分词(比如"age和":的边界),所以把前文和跳过的字符串拼成文本后重新分词,再继续。 FSMCache:按正则缓存编译结果,第一次见到某个正则时起一个线程去编译(init_fsm_in_background),请求到达时等它完成。编译一个正则要几秒到几十秒,放主线程会卡住整个调度。- jump-forward 需要在调度循环里把请求从 batch 里摘出来、改输入、重新分词、再放回去,和重叠调度、投机解码、分块 prefill 等机制交织,维护成本高;xgrammar 这类语法库在 C++ 侧实现了同样的"找确定性字符串"(
find_jump_forward_string),SGLang 只需调用接口。今天BaseGrammarObject仍保留try_jump_forward等方法,由后端决定是否支持。
先看一个六格小剧场,再读正文:
第一版:复制 Outlines,采样时做掩码
初始提交的 srt/constrained/ 有四个文件,fsm.py 和 regex.py 的开头写明了来源:
| python/sglang/srt/constrained/fsm.py @ 22085081bb L1-2 | |
|---|---|
Outlines 的做法:interegular 把正则解析成 FSM,create_fsm_index_tokenizer 为每个状态算出允许的 token 集合(states_to_token_maps)。SGLang 复制这部分代码而不是直接依赖 Outlines,是因为当时 Outlines 的接口变化快、依赖重,而且 SGLang 想在 FSM 上做自己的事(后面的 jump-forward 就需要访问 FSM 的内部转移表)。
编译一个正则很慢,所以有一个带后台线程的缓存:
请求到达时(handle_generate_request)如果带了 regex,调度器 get_fsm(regex):第一次见到的正则起线程编译,event.wait() 等它完成;之后命中缓存直接返回。注意 get_fsm 是阻塞的——调度循环会在这里停下来等编译,这是初版可接受的简化(论文的实验里一个正则会被一批请求复用)。采样时的掩码在 Batch.sample 里:
    def sample(self, logits: torch.Tensor):
        # Post process logits
        logits = logits.contiguous()
        logits.div_(self.temperatures)
        logits.add_(self.logit_bias)

        has_regex = any(req.regex_fsm is not None for req in self.reqs)
        if has_regex:
            allowed_mask = torch.empty_like(logits[0], dtype=torch.bool)
            for i, req in enumerate(self.reqs):
                if req.regex_fsm is not None:
                    allowed_mask.zero_()
                    allowed_mask[
                        req.regex_fsm.allowed_token_ids(req.regex_fsm_state)
                    ] = 1
                    logits[i].masked_fill_(~allowed_mask, float("-inf"))
...
        if has_regex:
            batch_next_token_ids_cpu = batch_next_token_ids.cpu().numpy()
            for i, req in enumerate(self.reqs):
                if req.regex_fsm is not None:
                    req.regex_fsm_state = req.regex_fsm.next_state(
                        req.regex_fsm_state, batch_next_token_ids_cpu[i]
                    )
逐个请求构造布尔掩码、masked_fill_ 成负无穷,采样后在 CPU 上推进状态。每个带正则的请求每步一次 Python 循环加一次 GPU 掩码——简单,但在大 batch 下是明显的开销,后来被批量化的 fill_vocab_mask_batched 和 GPU 上的 apply_vocab_mask 取代。
三周后:fast forward,然后改名 jump-forward
2024-01-25 的提交 fast regex decode(01ee0fbc05)加入了论文说的压缩 FSM,当时叫 fast-forward;2 月 5 日 jump-forward rename (#144) 统一改名(同一天 LMSYS 发了介绍 jump-forward 的博客)。看一下这条线上的提交:
REF=${REF:-29f6d408c0}
git log --reverse --date=short --format='%ad  %h  %s' "$REF" | grep -iE 'jump.?forward|fast regex' | cut -c1-100
2024-01-25  01ee0fbc05  fast regex decode
2024-02-05  26f0bedc8f  jump-forward rename (#144)
2024-02-09  4d303c4fa3  Fix token usage with jump forward (#174)
2024-02-15  63ba630bbb  Refactor decoding logprob and add completion_tokens_wo_jump_forward (#189)
2024-06-16  ad5f04d6ce  Fix the Jump-Forward with Chinese (#551)
2024-07-19  7620cd37dd  Fix jump forward when streaming (#665)
2024-08-13  e205527cb1  Fix jump forward final state circular path bug. (#1084)
2024-10-12  9610fcd469  Fix the batch_is_full check for jump-forward decoding (#1654)
2025-03-03  935cda944b  Misc clean up; Remove the support of jump forward (#4032)
v0.1.12(2024-02-11)的 jump_forward.py 是一个独立的 JumpForwardMap:
它读 FSM 的转移表(fsm_info.transitions),找出每个"只有一条出边、且这条边只对应一个字符"的状态(state_to_jump_forward),有多条出边或者一条边对应多个字符的状态标记为 dirty。查询时从当前状态沿这些单一出边一直走,把沿途字符拼起来,就是可以直接跳过的字符串。编译结果用 disk_cache 存到磁盘(Disk FSM cache (#63),2024-01-21 加入,因为同一个正则重启后还要用)。
调度器每步 decode 之前检查哪些请求可以跳:
可以跳的请求被从 batch 里摘出来:先把它已有的 KV 插进基数树(和请求结束时一样),释放槽位和请求槽,然后 jump_forward_and_retokenize——把前文和跳过的字符串拼成文本、重新分词、得到新的 input_ids——再放回等待队列,下一轮作为新的 extend 请求进入,前缀自然从树上命中。这个设计很聪明:跳跃解码被归约成了"一次带前缀缓存的新请求",不需要在 batch 内部改张量。代价也在这里:请求要经历"摘出 → 插树 → 重分词 → 重新准入",和 batch 的其他机制耦合很深。
重新分词的必要性,在博客里举了例子:直接把跳过的字符串按字符追加会把 "name": 分成和模型训练时不同的 token 边界,模型后面的输出质量会下降;重新分词后前缀的 token 可能和原来略有不同(博客测得约 4% 的 token 边界会变),所以要用树上的匹配而不是假设前缀完全相同。2024-06-16 的 Fix the Jump-Forward with Chinese (#551) 修的就是多字节字符在这条路径上的边界问题。
换回库,再换新库
2024-02-09 的 import outlines (#168) 删掉复制的 FSM 代码、直接依赖 Outlines(之后是一连串 "Pin outlines version"、"Support outlines > 0.0.31"、"Fix outlines-0.0.35 incompatibility"——依赖一个快速变化的库的代价)。8 月 JSON constrained support (#1125) 加了 JSON schema。10 月 26 日 Support both xgrammar and outlines for constrained decoding (#1752) 引入第二个后端,v0.4 的博客称 JSON 解码快了 10 倍;11 月 Fix grammar backend for tensor parallelism (#2020) 抽出 base_grammar_backend.py,后端从此可插拔;2025-02-26 Support llguidance (#3298) 加了第三个后端;2025-02-28 integrate Structural Tag in xgrammar backend for function calling (#3566) 把约束解码用到了函数调用上。
看一下目录在四个时间点的样子:
REF=${REF:-29f6d408c0}
for r in 22085081bb v0.1.12 v0.4.0 "$REF"; do
  echo "== $r"; git ls-tree --name-only "$r" python/sglang/srt/constrained/ | sed 's|python/sglang/srt/constrained/|   |'
done
== 22085081bb
   fsm.py
   fsm_cache.py
   regex.py
   tokenizer.py
== v0.1.12
   __init__.py
   base_cache.py
   fsm_cache.py
   jump_forward.py
== v0.4.0
   __init__.py
   base_grammar_backend.py
   outlines_backend.py
   outlines_jump_forward.py
   xgrammar_backend.py
== 29f6d408c0
   base_grammar_backend.py
   grammar_manager.py
   json_schema_validation.py
   llguidance_backend.py
   outlines_backend.py
   outlines_jump_forward.py
   reasoner_grammar_backend.py
   torch_ops
   utils.py
   xgrammar_backend.py
今天的接口是 BaseGrammarObject,每个后端实现同一组方法:
class BaseGrammarObject:
    def __init__(self):
        self._finished = False
        self.grammar_stats = None
        self.current_token = None

    def maybe_init_reasoning(self, reasoning: bool):
        pass

    def accept_token(self, token: int) -> None:
        """
        Accept a token in the grammar.
        """
        raise NotImplementedError()

    def rollback(self, k: int):
        raise NotImplementedError()

    def is_terminated(self):
...
    def try_jump_forward(self, tokenizer) -> Optional[Tuple[List[int], str]]:
        """
        Try to jump forward in the grammar.

        Returns:
            A jump forward helper which may be used in `jump_forward_str_state`.
            None if the jump forward is not possible.
        """
        raise NotImplementedError()

    def jump_forward_str_state(self, helper: Tuple[List[int], str]) -> Tuple[str, int]:
        """
        Jump forward for the grammar.

        Returns:
            A tuple of the jump forward string and the next state of the grammar
            (which can be used in `jump_and_retokenize` if needed).
        """
        raise NotImplementedError()

    def jump_and_retokenize(
        self, old_output_ids: List[int], new_output_ids: List[int], next_state: int
    ) -> None:
        """
        Jump forward occurs, and update the grammar state if needed.
        """
        raise NotImplementedError()
try_jump_forward / jump_forward_str_state / jump_and_retokenize 三个方法就是 jump-forward 留下的接口;xgrammar 后端的实现只是转发给它的 matcher:
删掉调度器里的 jump-forward
2025-03-03 的 Misc clean up; Remove the support of jump forward (#4032) 改了 41 个文件、删了 426 行。看它的提交信息和删掉的东西:
git show --format='%ad %h %an%n%s%n%b' --date=short --stat=90 935cda944b | grep -v '^$' | grep -iE 'jump|^2025|Misc|constrained|schedule|infer|batch' | head -20
2025-03-03  935cda944b  Lianmin Zheng
Misc clean up; Remove the support of jump forward (#4032)
 ...atch_inference.py => offline_batch_inference_eagle.py} |   2 +-
 python/sglang/srt/constrained/base_grammar_backend.py     |   1 -
 python/sglang/srt/constrained/outlines_backend.py         |   7 +-
 python/sglang/srt/layers/attention/flashinfer_backend.py  |   3 +-
 .../sglang/srt/layers/attention/flashinfer_mla_backend.py |   3 +-
 python/sglang/srt/managers/schedule_batch.py              | 126 +---------
 python/sglang/srt/managers/scheduler.py                   |  59 -----
 python/sglang/srt/model_executor/forward_batch_info.py    |   2 +-
 test/srt/test_ebnf_constrained.py                         |   8 -
 test/srt/test_json_constrained.py                         |  22 --
 test/srt/test_regex_constrained.py                        |  17 --
删除的理由可以从同期的代码推断:到 2025 年初,调度器里已经有重叠调度(CPU 调度和 GPU 前向错开一步)、EAGLE 投机解码(一步验证多个 token)、分块 prefill,每一个都要和"把请求从 batch 里摘出来再放回去"的 jump-forward 路径对接;而 xgrammar 在 C++ 里实现了同样的 find_jump_forward_string,并且把掩码计算也做在了 C++ 侧。于是 SGLang 保留接口、删掉自己的实现:这就是"先自研、后用库"的一个典型。论文里的技术没有消失,它变成了语法库的功能,SGLang 回到"调度与缓存"这个主业上。
设计取舍
| 阶段 | 选择 | 得 | 失 |
|---|---|---|---|
| 2024-01 | 复制 Outlines 的 FSM 代码 | 能访问转移表,做 jump-forward | 要跟着上游修 bug |
| 2024-01-25 | jump-forward 归约成"新请求" | 不改 batch 内部张量,复用前缀缓存 | 请求要摘出、重分词、重准入,耦合深 |
| 2024-02 | 改为依赖 Outlines 库 | 少维护一份代码 | 版本兼容反复出问题 |
| 2024-10 | 多后端(xgrammar) | 速度,JSON schema、EBNF、结构化标签 | 要维护后端抽象 |
| 2025-03 | 删掉自己的 jump-forward | 调度器简化 | 功能依赖后端是否支持 |
后来怎么样了
- 2025 年 6 月前后,约束解码和"推理模型"结合:
reasoner_grammar_backend.py让语法只在</think>之后生效; - 掩码的应用从每请求一次
masked_fill_变成批量的fill_vocab_mask_batched+ 一次 GPU kernel(constrained/torch_ops/); grammar_manager.py统一管理编译缓存和失败回退(编译失败的语法返回InvalidGrammarObject而不是让请求卡住);- 函数调用(第 20 章)的解析在
function_call/和 Rust 网关里,约束解码只负责"生成阶段保证格式"。
练习
1. 后台编译的竞态。 初版 FSMCache.get_fsm 里,两个请求同时带来同一个新正则时会发生什么?会编译两次吗?
参考答案
不会:init_fsm_in_background 先检查 regex not in self.cache,第一次调用就放进一个空的 FSMCacheEntry 并起线程,第二次调用看到键已存在直接 event.wait()。但这依赖调度循环是单线程的(两次调用不会同时进入 if);初版的调度确实在一个线程里,所以成立。
2. jump-forward 的收益条件。 根据 check_for_jump_forward 的代码,什么样的正则 / JSON schema 能从 jump-forward 得到收益?len(jump_forward_str) <= 1 为什么跳过?
参考答案
有长段确定文本的模式(固定键名的 JSON、带固定前缀的句子);每跳一次要付出摘出、重分词、重新 extend 的代价,跳过的字符串只有一个字符时收益抵不过开销,所以跳过。
3. 自己验证删除的影响。 在 935cda944b 的父提交和它本身分别数一数 managers/ 和 constrained/ 下含 jump_forward 的行数。
参考思路
git grep -c jump_forward 935cda944b^ -- python/sglang/srt/managers python/sglang/srt/constrained 与 git grep -c jump_forward 935cda944b -- ... 对比;会看到调度器侧的引用基本清零,constrained/ 里只剩后端接口。
怎么讲清楚
"结构化输出怎么做、怎么加速?"——基本做法是 FSM 掩码(预计算每个状态允许的 token,每步一次掩码);加速点是跳过确定性片段(压缩 FSM / jump-forward),难点是重新分词和与调度器的耦合。可以补一句 SGLang 的演变:自己实现过 jump-forward,后来交给 xgrammar 这样的语法库,调度器只保留接口——说明你知道这个功能"应该放在哪一层"。
小结
- 初版复制 Outlines 的 FSM,
FSMCache后台编译,Batch.sample逐请求掩码。 - jump-forward 把"跳过确定字符串"归约成一次带前缀缓存的新请求,必须重新分词。
- 后端从复制代码 → Outlines 库 → xgrammar / llguidance 可插拔;2025-03 删掉调度器里的 jump-forward,功能移入语法库。
- 这是"论文想法 → 自研实现 → 交给专门的库"的完整样本。
发现错误或有更好的写法?在 GitHub 上编辑此页提交问题