RadixAttention 第一版:220 行的基数树逐行读
RadixAttention 是 SGLang 的招牌,而它的第一版只有 220 行:一个 TreeNode、一个按字符比较的 match、递归的匹配与插入、按最近访问时间淘汰叶子的 evict,以及一对引用计数函数。这一章把 22085081bb 的 radix_cache.py 逐段读完,看它怎样和调度器配合,再读发布 8 天后就修掉的一个匹配 bug——一个很好的例子,说明"看起来对"的树操作有多容易错。最后把它和今天 820 行、带页对齐、哈希和多种淘汰策略的版本对照。
自测:能答上来就可以跳过本章
- 树的节点上存的"键"和"值"分别是什么?为什么键是 token 序列的一段而不是一个 token?
- 匹配到一条边的中间时会发生什么?插入时呢?
- 淘汰策略是什么?哪些节点不能被淘汰?
evictable_size是怎么维护的? - 调度器在什么时候调用
match_prefix、inc_ref_counter、insert、dec_ref_counter?
自测参考答案(先自己答,再展开对照)
- 键是一段 token id 序列(父节点到该节点的边上的 token),值是这些 token 的 KV 在池里的槽位索引(一个张量)。基数树(压缩前缀树)把只有一个孩子的链压成一条边,节点数和内存都远少于每个 token 一个节点的 trie,匹配时按边逐段比较。
- 匹配到边的中间(新序列和这条边只有部分相同)时,把这条边在分叉点切成两段:新建一个中间节点承接前半段,原节点只保留后半段;匹配结果到中间节点为止。插入时同样先分裂再在中间节点下挂新边。
- 收集所有叶子放进按
last_access_time排序的最小堆,从最久未访问的叶子开始删,直到释放够num_tokens;引用计数大于 0(有运行中的请求在用)的节点跳过;删掉一个叶子后如果父节点变成叶子,把父节点也放进堆。evictable_size在插入新节点时加上它的长度,在节点被引用(计数从 0 变 1)时减去、解除引用(从 1 变 0)时加回,删除叶子时减去。 - 组 batch 时先对每个等待的请求
match_prefix;决定接纳时inc_ref_counter(last_node)锁住路径;请求结束时insert(input_ids + output_ids, 槽位)把整条序列放进树,释放树里已有部分对应的池槽位,再dec_ref_counter(last_node)解锁。
先看一个六格小剧场,再读正文:
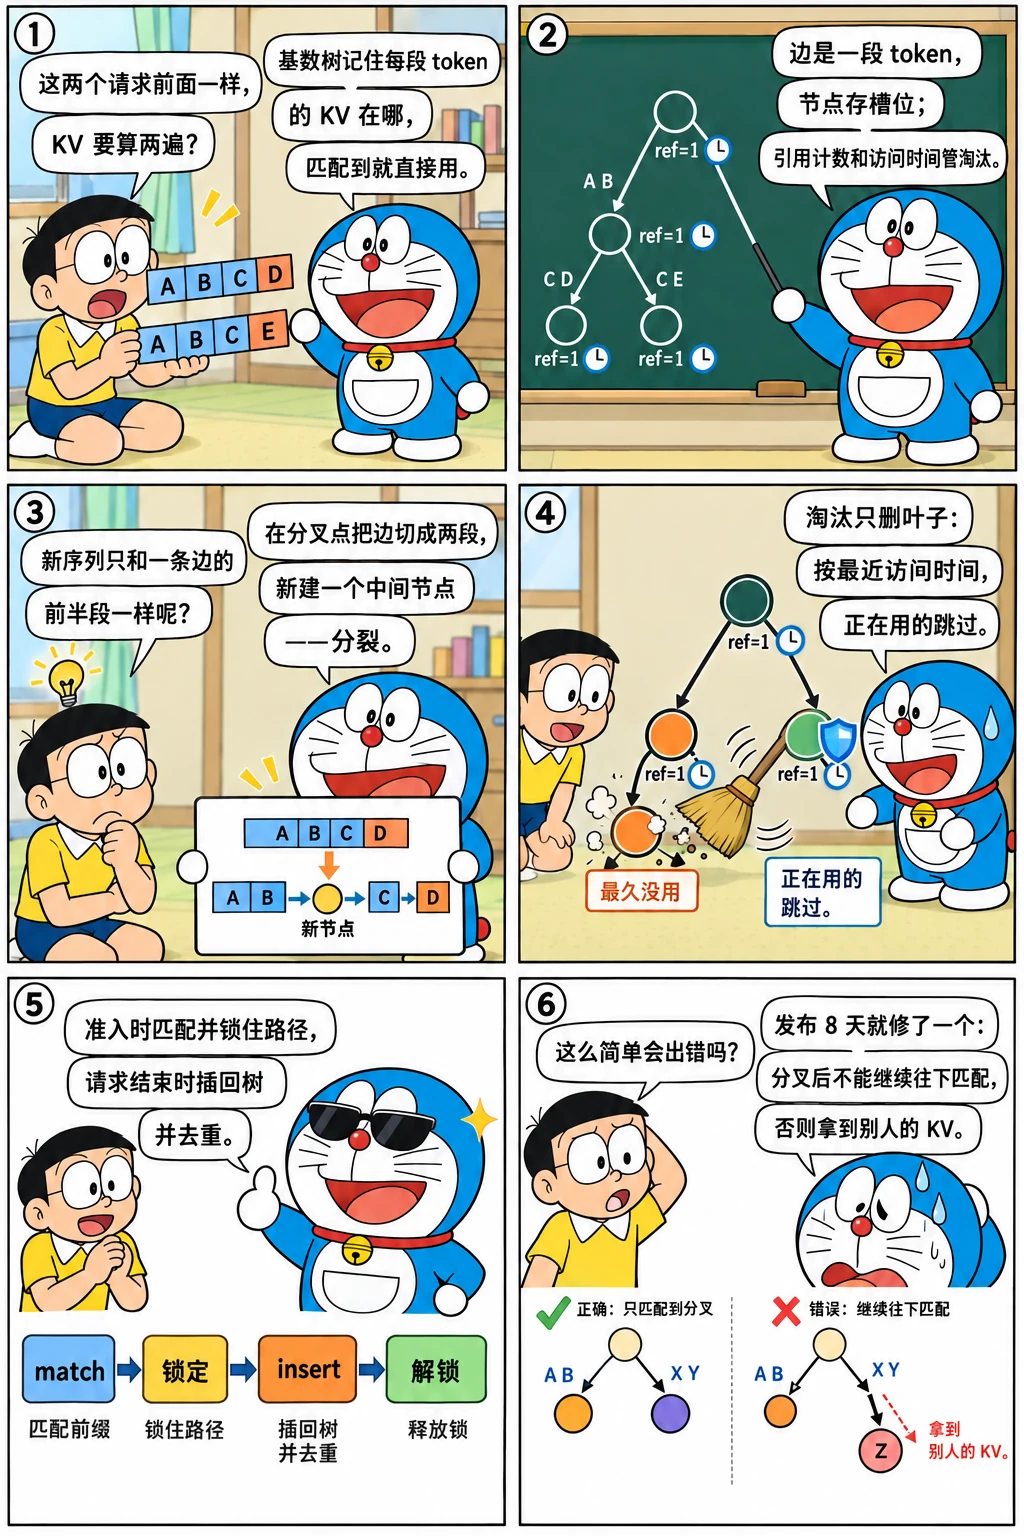
节点与匹配
TreeNode 的 children 是 defaultdict,键是一段 token 序列(元组),值是子节点;value 是这段 token 对应的槽位索引张量;ref_counter 记录有多少运行中的请求经过这个节点;last_access_time 用于 LRU;__lt__ 让节点能直接放进 heapq。match(key, seq) 返回两个序列的公共前缀长度,是整棵树唯一的比较操作。
公开接口只有六个:match_prefix、insert、evict、inc_ref_counter、dec_ref_counter、evictable_size(外加调试用的 pretty_print 和 total_size):
match_prefix 返回两样东西:命中的槽位索引(各段 value 拼起来的张量)和 last_node(命中路径的最后一个节点)。调度器后面用 last_node 做引用计数。disable 是 --model-mode no-cache 的实现:匹配永远为空,插入永远"全部已存在"(返回 len(key),调用方据此释放全部槽位)。
递归匹配、分裂与插入
_match_prefix_helper 在当前节点的孩子里找一条和 key 有公共前缀的边(最多一条,因为兄弟边的首 token 互不相同),然后分两种情况:公共前缀短于这条边就分裂,到此为止;否则整条边命中,递归进孩子继续匹配剩下的 key。_split_node 把一条边切成两段:新建 new_node 承接前 split_len 个 token(值也切开),继承原节点的引用计数(因为经过原节点的请求必然也经过它),原节点变成 new_node 的孩子。
插入是同样的结构:
返回值是"树里已经有的前缀长度":调用方据此知道这条序列的前多少个 token 的 KV 已经有一份,可以把自己那份槽位释放掉(去重)。新建节点时 evictable_size_ += len(value),因为新节点没有引用、可以淘汰。
淘汰与引用计数
evict 的策略是叶子优先的 LRU:收集所有叶子,按最近访问时间建最小堆,弹出最久未访问的叶子,引用计数大于 0 就跳过,否则调用 evict_callback(调度器传入的 token_to_kv_pool.free)释放槽位、删掉叶子;父节点因此变成叶子的话也进堆。只淘汰叶子是必然的:内部节点的 KV 是它所有后代的前缀,删了内部节点后代就不完整了。
引用计数沿路径向上累加:inc_ref_counter(node) 从 node 走到根,每个节点计数加一;计数从 0 变 1 的节点离开"可淘汰"集合,所以 evictable_size_ 要减去它的长度,函数返回这个变化量(负数),调度器用它修正"可用空间"的估计(上一章的准入逻辑)。dec_ref_counter 反过来。
调度器怎么用它
树本身不知道请求的存在,四个调用点都在 model_rpc.py 里。组 batch 时先匹配、后锁定:
        for req in self.forward_queue:
            prefix_indices, last_node = self.tree_cache.match_prefix(req.input_ids)
            if req.return_normalized_logprob:
                prefix_indices = prefix_indices[: req.normalized_logprob_start_len]
            req.adjust_input_len = len(req.input_ids) - len(prefix_indices)
            req.prefix_indices = prefix_indices
            req.last_node = last_node
...
                delta = self.tree_cache.inc_ref_counter(req.last_node)
                available_size += delta

                if not (
                    req.adjust_input_len + req.max_new_tokens() + new_batch_total_tokens
                    < available_size
                ):
                    delta = self.tree_cache.dec_ref_counter(req.last_node)
                    available_size += delta
                else:
                    self.token_to_kv_pool.add_refs(req.prefix_indices)
                    can_run_list.append(req)
请求结束时插入并去重:
        # Remove finished reqs
        if finished_indices:
            # Update radix cache
            req_pool_indices_cpu = batch.req_pool_indices.cpu().tolist()
            for i in finished_indices:
                req = batch.reqs[i]
                req_pool_idx = req_pool_indices_cpu[i]
                token_ids = tuple(req.input_ids + req.output_ids)
                seq_len = len(token_ids) - 1
                indices = self.req_to_token_pool.req_to_token[req_pool_idx, :seq_len]
                prefix_len = self.tree_cache.insert(token_ids, indices.clone())

                self.token_to_kv_pool.free(indices[:prefix_len])
                self.req_to_token_pool.free(req_pool_idx)
                self.tree_cache.dec_ref_counter(req.last_node)
token_ids 是输入加输出的整条序列,seq_len = len - 1 是因为最后一个 token 的 KV 还没算(它是刚采样出来、还没送进模型的那个)。insert 返回已存在的前缀长度 prefix_len,这部分槽位是重复的,释放掉;剩下的槽位现在归树管。然后释放请求槽、解除锁定。
缓存感知的调度策略在 scheduler.py 里,只有 73 行:
默认 lpm(longest prefix match):按命中长度降序。weight 策略是论文定理的实现:先把等待请求按 last_node 分组,再从根开始递归,每个节点的权重是它子树里挂的请求数,按权重大的孩子优先深度遍历——这样同一子树的请求连在一起处理,前缀留在缓存里的时间最短。new_token_estimation_ratio 对 fcfs 用 0.5,其他策略用 0.4:缓存感知的策略命中更多、实际新增更少,可以估得更乐观。
发布 8 天后的 bug
2024-01-16 的 fix radix cache match (#7) 是整个仓库第七个 PR,只改了两行:
git show --format='%ad %h %an %s' --date=short 01ca82d765 -- python/sglang/srt/managers/router/radix_cache.py | sed -n '1p;/^@@/,$p'
2024-01-16  01ca82d765  Liangsheng Yin  fix radix cache match (#7)
@@ -116,12 +116,12 @@ class RadixCache:
         for c_key, child in node.children.items():
             prefix_len = match(c_key, key)
             if prefix_len != 0:
-                if prefix_len == len(key) and prefix_len != len(c_key):
+                if prefix_len < len(c_key):
                     new_node = self._split_node(c_key, child, prefix_len)
                     value.append(new_node.value)
                     last_node[0] = new_node
                 else:
-                    value.append(child.value[:prefix_len])
+                    value.append(child.value)
                     last_node[0] = child
                     self._match_prefix_helper(child, key[prefix_len:], value, last_node)
                 break
原来的条件是"key 整个被这条边包含、且比边短才分裂",否则取边的前 prefix_len 个 token 并递归进孩子。错在第二种情况里包含了"key 比边长、但只和边的前半段相同"的情形:此时匹配已经在边中间分叉,不该再往下走,可往下走之后 key 剩下的部分会去和孙子节点比较,一旦碰巧有公共前缀,就把一段上下文完全不同的 KV 当成命中返回。用一个纯 Python 的小模型复现(键用字符串,值就是字符本身,便于看出错在哪):
"""复现 #7 修掉的匹配 bug:树里有 "Hello_L.A.!" → "world",查 "Hello_world"。"""
from collections import defaultdict


class Node:
    def __init__(self, value=""):
        self.children, self.value = {}, value


def match(a, b):
    i = 0
    while i < min(len(a), len(b)) and a[i] == b[i]:
        i += 1
    return i


def insert(node, key):
    for ck, child in node.children.items():
        n = match(ck, key)
        if n == len(ck):
            return insert(child, key[n:]) if n < len(key) else None
        if n:
            mid = Node(ck[:n]); mid.children[ck[n:]] = child; child.value = ck[n:]
            del node.children[ck]; node.children[ck[:n]] = mid
            return insert(mid, key[n:])
    if key:
        node.children[key] = Node(key)


def match_prefix(node, key, buggy):
    out = []
    for ck, child in node.children.items():
        n = match(ck, key)
        if n:
            if (n == len(key) and n != len(ck)) if buggy else (n < len(ck)):
                out.append(ck[:n])                      # 分裂(这里只取前半段,省略真正的分裂)
            else:
                out.append(ck[:n] if buggy else ck)
                out += match_prefix(child, key[n:], buggy)
            break
    return out


root = Node()
insert(root, "Hello_L.A.!")
insert(root, "Hello_L.A.!world")
for buggy in (True, False):
    hit = "".join(match_prefix(root, "Hello_world", buggy))
    print(f"{'修复前' if buggy else '修复后'}:命中 {hit!r}({len(hit)} 个 token)")
修复前,Hello_world "命中"了 11 个 token:前 6 个是对的(Hello_),后 5 个 world 来自 Hello_L.A.!world 这条序列——那是 "Hello_L.A.!" 之后的 "world",KV 完全不同。修复后只命中 Hello_。两行的修正:只要公共前缀短于这条边就分裂、停止;整条边命中时追加整条边的值(而不是切片)再递归。这类错误单元测试很难覆盖(需要恰好构造"分叉后又碰巧匹配"的序列),所以树操作的每一个分支都值得像这样手动推一遍。
设计取舍
初版基数树的几个选择,以及它们为什么合理:
- 叶子 LRU 而不是全局 LRU。 内部节点不能单独删,所以淘汰只在叶子上发生;用
last_access_time排序叶子等价于"最久未用的完整路径优先",实现只要一个堆。 - 引用计数而不是"正在运行就不淘汰"的标记。 多个请求可以共享同一条路径,计数能正确表达"最后一个用的人走了才可淘汰"。
- 插入在请求结束时,而不是 prefill 完成时。 简单,但有一个代价:运行中的请求的前缀对别的请求不可见(同一批里的相同前缀要各算一遍)。2024-12-11 的
in batch prefix caching by delay scheduling (#2442)和后来的cache_unfinished_req才补上这一点。 - 按 Python 元组比较。
match是纯 Python 循环,每次匹配 O(前缀长度)。论文测得 100 个请求的树操作共 0.2 秒,当时够用;后来 2024-04 的Optimize radix tree matching (#364)和 2025 年的 C++ / Rust 树都是在这一点上做文章。
后来怎么样了
这个文件的历史能直接 --follow 出来(它在 #807 时从 managers/router/ 搬到了 mem_cache/):
REF=${REF:-29f6d408c0}
f=python/sglang/srt/mem_cache/radix_cache.py
echo "提交数:$(git log --follow --format=%h "$REF" -- $f | wc -l)"
for y in 2024 2025 2026; do echo "  $y:$(git log --follow --date=short --format=%ad "$REF" -- $f | grep -c "^$y")"; done
echo "今天的行数:$(git show "$REF:$f" | wc -l)"
echo "mem_cache/ 的 Python 文件数:$(git ls-tree -r --name-only "$REF" -- python/sglang/srt/mem_cache | grep -c '\.py$')"
几个节点:
| 时间 | 提交 | 变化 |
|---|---|---|
| 2024-04-18 | Optimize radix tree matching (#364) |
匹配改成更快的实现,孩子按首 token 索引 |
| 2024-07-29 | Code structure refactor (#807) |
搬进 mem_cache/,与 memory_pool.py 同目录 |
| 2025-02-23 | Hierarchical Caching for SGLang (#2693) |
hiradix_cache.py 继承它,节点可以在 GPU / CPU 之间搬 |
| 2025-03-12 | Support page size > 1 (#4356) |
键按页对齐,匹配以页为单位 |
| 2025-08-11 | HiCache Storage: generate hash when inserting new nodes (#9053) |
节点带哈希值,作为外部存储的键 |
| 2025-09 → 2026-03 | #10190、#11506、#18843 |
淘汰策略插件化:LRU、LFU、SLRU…… |
| 2026-01 → 2026-03 | [RadixTree][N/N Refactor] 系列 |
统一的插入 / 淘汰参数、锁接口;滑动窗口注意力的 SWARadixTree |
今天的 TreeNode 长这样:
对比初版:多了 id、priority、hit_count、host_value(CPU 侧的副本)、hash_value(存储键)、lock_ref 取代了 ref_counter、last_access_time 用单调时钟(2025-05-17 的 #6211 修正了用墙钟导致的排序异常)。键也从元组变成了 RadixKey,支持页对齐和为滑动窗口准备的"二元组视图"。但 _match_prefix_helper、_split_node、_insert_helper、evict 四个函数的名字和结构从 2024 年 1 月保留到现在。
练习
1. 为什么插入要返回已存在的长度。 读 _insert_helper 的三个 return,解释每种情况返回值的含义,以及调用方拿到它之后释放的是哪些槽位。
参考答案
整条边命中且 key 也到头:返回 prefix_len(整条序列都已存在);整条边命中但 key 还有剩余:返回这条边的长度加递归结果;部分命中:分裂后返回命中部分加递归结果(递归到新节点下通常会新建边,返回 0)。调用方的 indices[:prefix_len] 就是这条请求里和树重复的那段槽位,释放后树里只保留一份 KV。
2. 淘汰的边界。 构造一种情况:evict(num_tokens) 结束时释放的 token 数小于 num_tokens。调度器此时会怎样?
参考答案
所有叶子都被引用(计数大于 0)或者树已空时,堆弹空了也凑不够。Batch.init_extend_batch 在 evict 之后再 alloc 一次,仍失败就打印 "Prefill out of memory." 并 exit()——初版直接退出进程。这也是为什么准入要预估未来需求:它靠"少接请求"而不是"抢占"来避免这里。后来的版本在这种情况下撤回(retract)部分 decode 请求。
3. 延迟插入的代价。 用 git show 9208618b3e 看 #2442 "in batch prefix caching by delay scheduling" 解决了什么问题、怎么解决的。
参考思路
同一批里的多个请求共享前缀时,初版会各自计算一遍(插入在请求结束时才发生)。#2442 在组 batch 时识别出"和运行中 / 本批其他请求共享长前缀但树里还没有"的请求,把它们推迟到下一轮,让第一个请求先算完并插入,后面的就能命中。这是"插入时机"这个取舍的第一次修正。
怎么讲清楚
讲 RadixAttention 时按"结构 → 操作 → 和调度器的接口 → 取舍"四步:基数树的节点存一段 token 和对应槽位;匹配、插入都是"找有公共前缀的边、必要时在中间分裂";调度器在准入时匹配并锁定、结束时插入并去重;淘汰只在叶子上按 LRU 进行。然后主动提一个坑(比如发布 8 天就修的匹配 bug,或者页大小为 1 带来的元数据开销)和它后来的演变(页对齐、分层、多种淘汰策略),会比只背概念更能体现你读过代码。
小结
- 第一版 220 行:
TreeNode(键为 token 段、值为槽位、引用计数、访问时间)+ 递归匹配 / 插入 + 叶子 LRU 淘汰。 - 调度器在准入时匹配并锁定路径、结束时插入并去重;
evictable_size随引用计数变化,用于准入估计。 - 发布 8 天后修掉的匹配 bug 说明:边中间分叉后不能继续递归,否则会把别的上下文的 KV 当成命中。
- 四个核心函数的结构保留至今;变化发生在键(页对齐、哈希)、节点(锁、CPU 副本)和淘汰策略(插件化)上。
发现错误或有更好的写法?在 GitHub 上编辑此页提交问题